Research
Machine learning for medicine, chemistry and biology
Our group applies deep learning and computational modeling to problems at the intersection of chemistry, biology and medicine, from medicinal chemistry and drug safety to cancer genomics, image analysis and clinical studies. A hallmark of our work is close collaboration with experimental and clinical scientists to produce useful tools that enable more efficient discovery.
Drug metabolism and toxicity
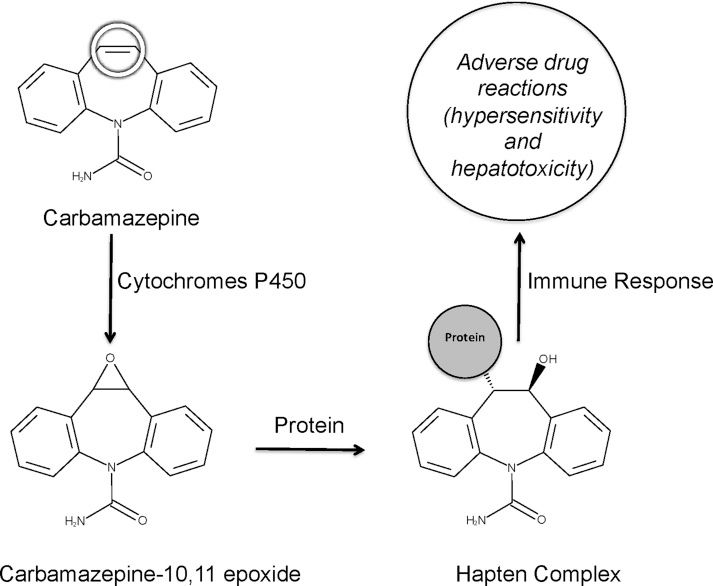
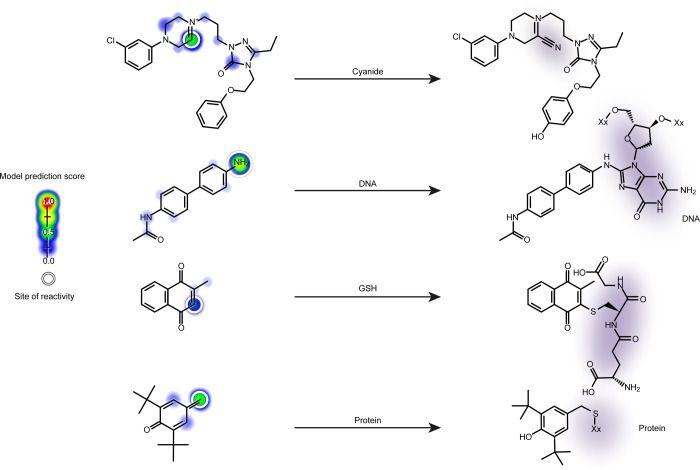
Many drugs fail, or are withdrawn, because the liver converts them into reactive metabolites that bind to proteins and DNA. Our group builds models that predict where on a molecule metabolism occurs, which reaction takes place, and whether the resulting metabolite is likely to be reactive.
This work began with XenoSite, a neural-network model of cytochrome P450 sites of metabolism. We showed that these models can be trained from ambiguous, region-level data where the exact site of metabolism is unknown, and the work grew to cover epoxidation, quinone formation, N-dealkylation, UGT conjugation, glutathione and macromolecule reactivity, and all of Phase I metabolism in a single model. More recent work chains these predictions together to infer full metabolic pathways and the structures of the metabolites they produce. Close collaborations with experimental pharmacologists test these predictions on drugs such as terbinafine, meloxicam and the NSAIDs. The XenoSite models are used by pharmaceutical companies to guide the design of safer medicines.
Key papers
- Modeling the Bioactivation and Subsequent Reactivity of DrugsChem Res Toxicol 2021;34(2):584-600DOIPubMedFree full text
- The Metabolic Rainbow: Deep Learning Phase I Metabolism in Five ColorsJ Chem Inf Model 2020;60(3):1146-1164DOIPubMedFree full text
- XenoNet: Inference and Likelihood of Intermediate Metabolite FormationJ Chem Inf Model 2020;60(7):3431-3449DOIPubMedFree full text
- Metabolic Forest: Predicting the Diverse Structures of Drug MetabolitesJ Chem Inf Model 2020;60(10):4702-4716DOIPubMedFree full text
- Deep Learning to Predict the Formation of Quinone Species in Drug MetabolismChem Res Toxicol 2017;30(2):642-656DOIPubMedFree full text
- Modeling Reactivity to Biological Macromolecules with a Deep Multitask NetworkACS Cent Sci 2016;2(8):529-37DOIPubMedFree full text
- Modeling Epoxidation of Drug-like Molecules with a Deep Machine Learning NetworkACS Cent Sci 2015;1(4):168-80DOIPubMedFree full text
- XenoSite: accurately predicting CYP-mediated sites of metabolism with neural networksJ Chem Inf Model 2013;53(12):3373-83DOIPubMed
Deep learning of molecular structure
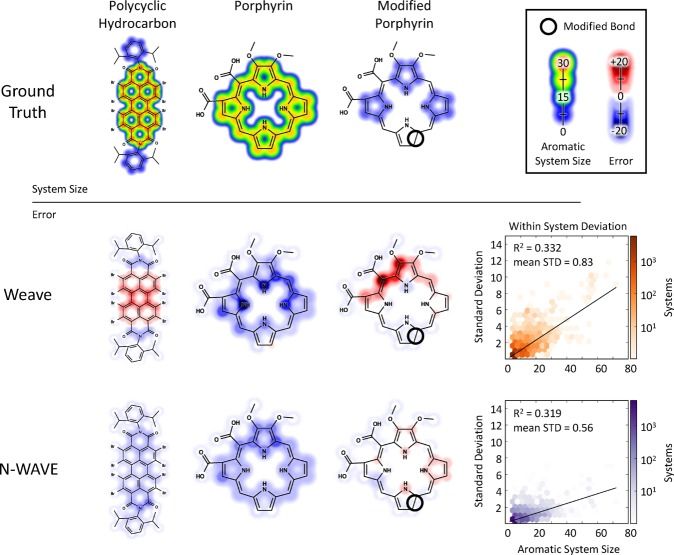
Predicting the behavior of small molecules and proteins requires representations that capture their underlying physics. We develop deep learning methods that learn these representations directly, rather than relying on hand-crafted descriptors.
Examples include a local-variable model of aromatic and conjugated systems, coordinate-free networks that reproduce quantum-chemical calculations, site-level bioactivity predictions built on learned quantum chemistry, and models that identify the structural determinants of protein properties by comparing structural ensembles.
Key papers
- Deep Learning Coordinate-Free Quantum ChemistryJ Phys Chem A 2021;125(40):8978-8986DOIPubMedFree full text
- Deep learning the structural determinants of protein biochemical properties by comparing structural ensembles with DiffNetsNat Commun 2021;12(1):3023DOIPubMedFree full text
- Site-Level Bioactivity of Small-Molecules from Deep-Learned Representations of Quantum ChemistryJ Phys Chem A 2020;124(44):9194-9202DOIPubMedFree full text
- Learning a Local-Variable Model of Aromatic and Conjugated SystemsACS Cent Sci 2018;4(1):52-62DOIPubMedFree full text
Chemical informatics
My early work, in Pierre Baldi’s group at UC Irvine, applied machine learning to predict the biological properties of small molecules. This included one of the first applications of kernel methods and support vector machines to chemical data, a widely cited study that helped spark a resurgence of chemical informatics within the bioinformatics community, and Influence Relevance Voting, an accurate and interpretable neural-network approach to virtual screening.
This work also produced algorithms for fast, exact search of chemical fingerprints, including the first sub-linear search algorithm, the first algorithmic progress in decades on this problem. It also produced ChemDB, one of the early public databases of commercially available chemicals, which together with ZINC and ChemBank renewed interest in chemical data and helped lead to PubChem. Later work examined how chemical data can be shared without revealing structures, and how to measure early retrieval performance (CROC).
Key papers
- A CROC stronger than ROC: measuring, visualizing and optimizing early retrievalBioinformatics 2010;26(10):1348-56DOIPubMedFree full text
- Influence relevance voting: an accurate and interpretable virtual high throughput screening methodJ Chem Inf Model 2009;49(4):756-66DOIPubMedFree full text
- Bounds and algorithms for fast exact searches of chemical fingerprints in linear and sublinear timeJ Chem Inf Model 2007;47(2):302-17DOIPubMedFree full text
- Kernels for small molecules and the prediction of mutagenicity, toxicity and anti-cancer activityBioinformatics 2005;21 Suppl 1:i359-68DOIPubMed
- ChemDB: a public database of small molecules and related chemoinformatics resourcesBioinformatics 2005;21(22):4133-9DOIPubMed
Screening and drug repurposing
Working with the screening team at the Broad Institute, we used economic theory to design more efficient high-throughput screens. Explicitly encoding costs and utility to direct confirmatory testing led to large efficiency gains, at times tripling the rate at which new active scaffolds were found.
Later work, funded first by Pfizer and then by GlaxoSmithKline, built software that used historical screening data to direct internal drug repurposing projects. It also addressed practical problems in screening data: missing measurements, hidden workflows in PubChem, and combining phenotypic with target-based assays. This work also produced the Scaffold Network Generator, an open-source tool for mining molecular collections.
Key papers
- Combined Analysis of Phenotypic and Target-Based Screening in Assay NetworksJ Biomol Screen 2014;19(5):782-90DOIPubMed
- Scaffold network generator: a tool for mining molecular structuresBioinformatics 2013;29(20):2655-6DOIPubMed
- Enhancing the rate of scaffold discovery with diversity-oriented prioritizationBioinformatics 2011;27(16):2271-8DOIPubMedFree full text
- Mining small-molecule screens to repurpose drugsBrief Bioinform 2011;12(4):327-35DOIPubMed
- An economic framework to prioritize confirmatory tests after a high-throughput screenJ Biomol Screen 2010;15(6):680-6DOIPubMedFree full text
Genomics and bioinformatics
Sequencing studies identify thousands of mutations in each tumor, but only a few drive the disease. We developed methods to distinguish drivers from passengers. These include a parsimony-guided, unsupervised approach to detecting driver mutations and a statistical test that identifies tumor suppressors and oncogenes from pan-cancer data.
With collaborators at the McDonnell Genome Institute, we also built deep learning tools that automate the refinement of somatic variant calls and improve neoantigen prediction by accounting for nearby variants. Other collaborations apply machine learning to gene expression, transcription factor binding and the microbiome. Related work outside genomics includes cryptosets, a way to securely measure the overlap between private datasets.
Key papers
- Accounting for proximal variants improves neoantigen predictionNat Genet 2019;51(1):175-179DOIPubMedFree full text
- A deep learning approach to automate refinement of somatic variant calling from cancer sequencing dataNat Genet 2018;50(12):1735-1743DOIPubMedFree full text
- Unsupervised detection of cancer driver mutations with parsimony-guided learningNat Genet 2016;48(10):1288-94DOIPubMedFree full text
- Statistically identifying tumor suppressors and oncogenes from pan-cancer genome-sequencing dataBioinformatics 2015;31(22):3561-8DOIPubMedFree full text
AI in pathology
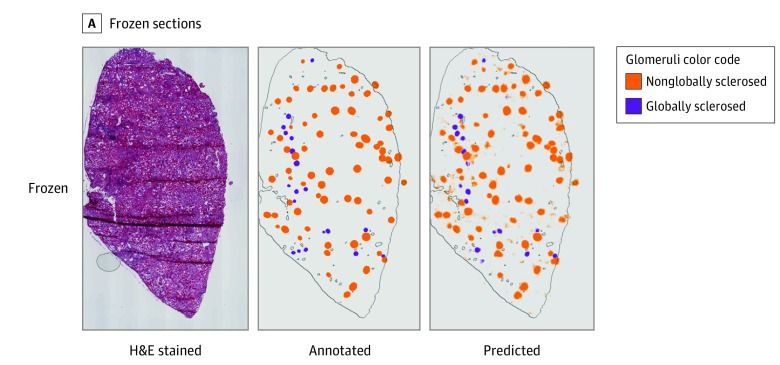
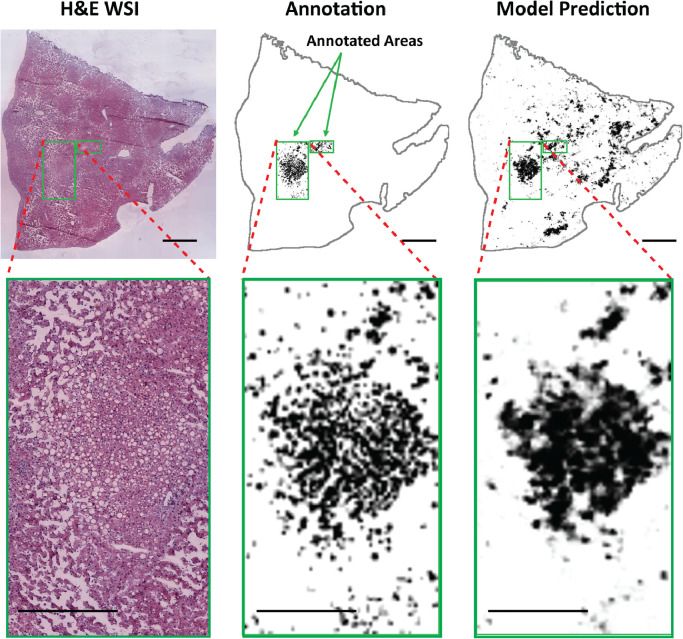
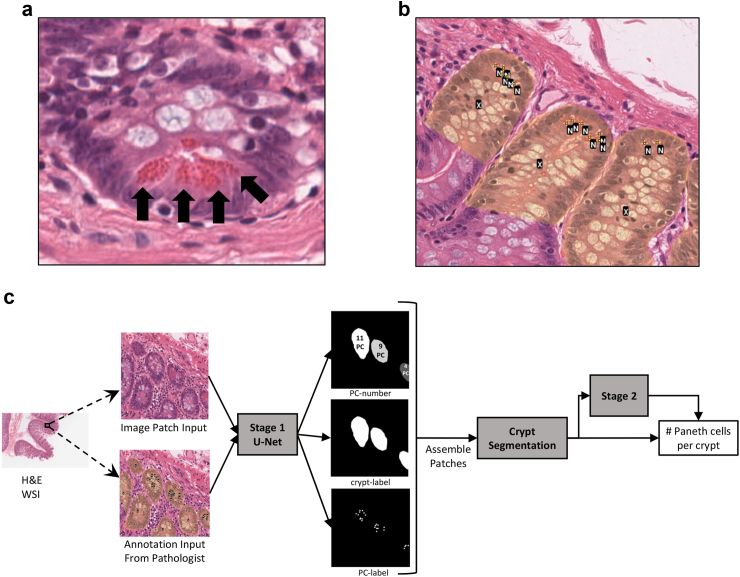
Our work has expanded into image analysis, where deep learning can guide critical clinical decisions. Pathologists often must decide, from a frozen section and under time pressure, whether a donor kidney or liver can be transplanted. We build deep learning systems that quantify these features consistently, including glomerulosclerosis in kidney biopsies, steatosis in donor livers, and Paneth cell density in inflammatory bowel disease, and that predict transplant outcomes.
Our group was among the first academic groups to deploy AI into a pathology workflow: the donor kidney biopsy model, developed with Joseph Gaut, is licensed to Trusted Kidney and is used in clinical practice by Mid-America Transplant.
Key papers
- Superior transplant recipient outcome prediction and pathology assessment using rapid deep learning applied to procurement kidney biopsiesSci Rep 2025;16(1):1921DOIPubMedFree full text
- Development of a deep learning algorithm for Paneth cell density quantification for inflammatory bowel diseaseEBioMedicine 2024;110:105440DOIPubMedFree full text
- Development and Validation of a Deep Learning Model to Quantify Glomerulosclerosis in Kidney Biopsy SpecimensJAMA Netw Open 2021;4(1):e2030939DOIPubMedFree full text
- Deep learning quantification of percent steatosis in donor liver biopsy frozen sectionsEBioMedicine 2020;60:103029DOIPubMedFree full text
- Deep Learning Global Glomerulosclerosis in Transplant Kidney Frozen SectionsIEEE Trans Med Imaging 2018;37(12):2718-2728DOIPubMedFree full text
AI in healthcare
Electronic health records hold patterns that no single clinician can see, but models trained on them must be trustworthy before they inform care. We apply machine learning to clinical data to find drug interactions, estimate risk and guide treatment, with an emphasis on models that clinicians can question and understand.
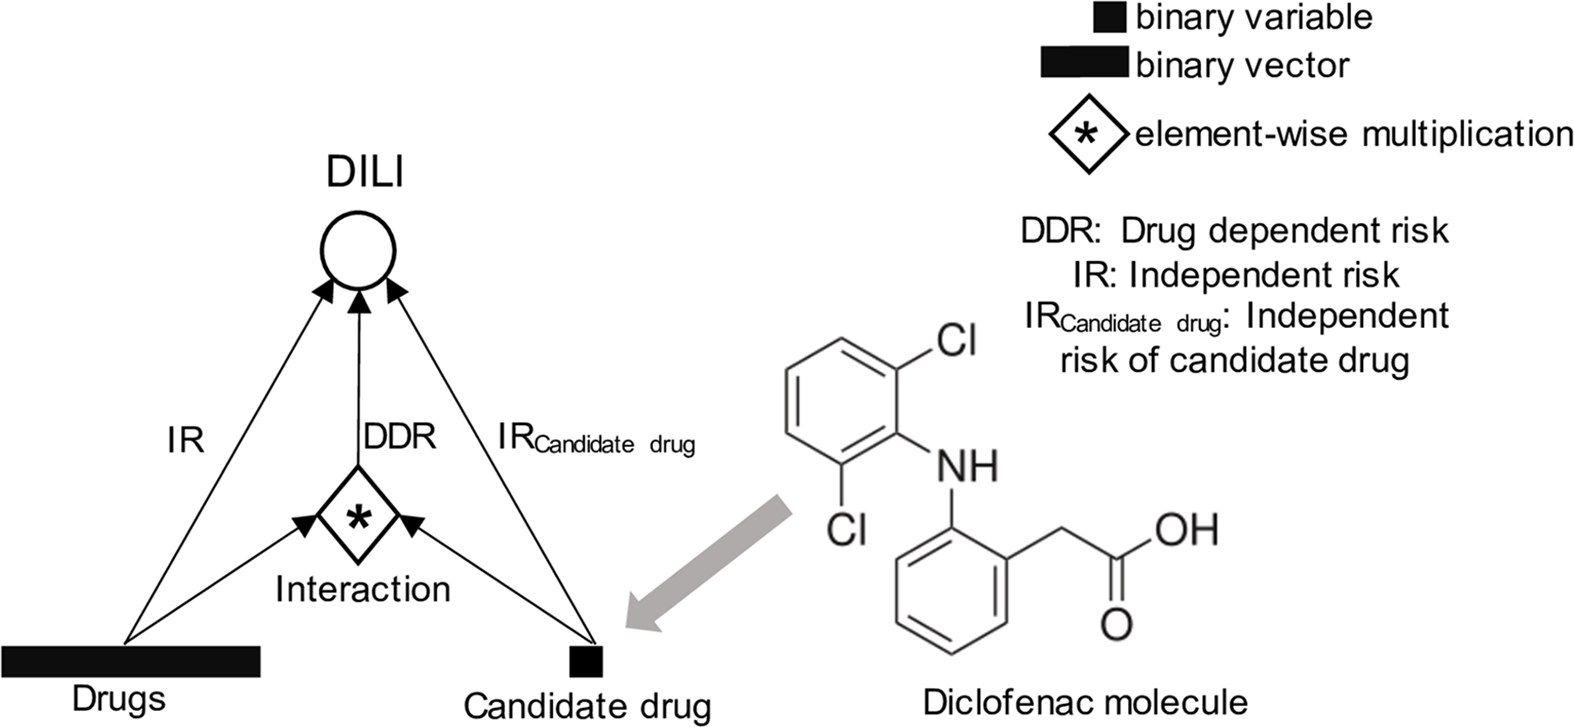
Examples include mining a retrospective EHR cohort to identify drugs that increase the risk of liver injury when combined with NSAIDs, “conversational” machine learning that surfaced a protective association between ondansetron and hospital-acquired venous thromboembolism, deep learning estimates of kidney function, and domain-constrained neural networks that guide patient-specific anesthetic dosing. We also study how race and socioeconomic status shape medical data, and how to recognize and mitigate their effects on models.
Key papers
- Domain Knowledge Inclusive Monotonic Neural Network Guides Patient-Specific Induction of General Anesthesia DosingA A Pract 2025;19(8):e02034DOIPubMed
- Understanding and mitigating the impact of race with adversarial autoencodersCommun Med (Lond) 2024;4(1):210DOIPubMedFree full text
- A Deep Learning Approach for the Estimation of Glomerular Filtration RateIEEE Trans Nanobioscience 2022;21(4):560-569DOIPubMed
- Machine learning liver-injuring drug interactions with non-steroidal anti-inflammatory drugs (NSAIDs) from a retrospective electronic health record (EHR) cohortPLoS Comput Biol 2021;17(7):e1009053DOIPubMedFree full text
- 'Black Box' to 'Conversational' Machine Learning: Ondansetron Reduces Risk of Hospital-Acquired Venous ThromboembolismIEEE J Biomed Health Inform 2021;25(6):2204-2214DOIPubMed
Research support
Our work has been supported by the National Institutes of Health (NLM, NIGMS, NIDDK, NCI and NIMH), by industry partners and by transplant organizations.
- Systematic discovery of bioactivation-associated structural alerts (NIGMS R01 GM140635; co-PI with Grover Miller)
- Data and tools for modeling metabolism and reactivity (NLM R01 LM012222; co-PI with Grover Miller)
- Computationally modeling the impact of ontogeny on drug metabolic fate (NLM R01 LM012482; co-PI with Grover Miller)
- Paneth cell phenotype as a predictive biomarker for ulcerative colitis (NIDDK R01 DK124274; co-investigator, PI Ta-Chiang Liu)
- Informatics tools for identification, prioritization, and clinical application of neoantigens (NCI U01 CA248235; co-investigator, PI Malachi Griffith)
- A deep learning model to improve pathologist interpretation of donor kidney biopsies (NIDDK STTR R41/R42, with PlatformSTL; co-investigator with Joseph Gaut)
- Early life adversity, biological embedding, and risk for developmental precursors of mental disorders (NIMH R01 MH113883; co-investigator, PI Joan Luby)
- Deep convolutional neural networks to enhance pathologic assessment of donor organs (Midwest Transplant Services)
- Industry research support from Pfizer and GlaxoSmithKline for drug repurposing from screening data